EIGHT WALKTHROUGHS
The AI stack
How LLMs work, from a data-centre campus down to one tensor core, to predict the next token.
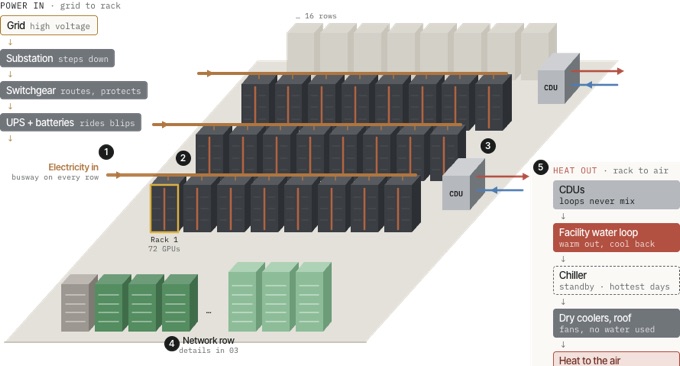
A data centre, top down
Explore what’s in a data centre: from the campus down to inside one GPU tensor core.
Start →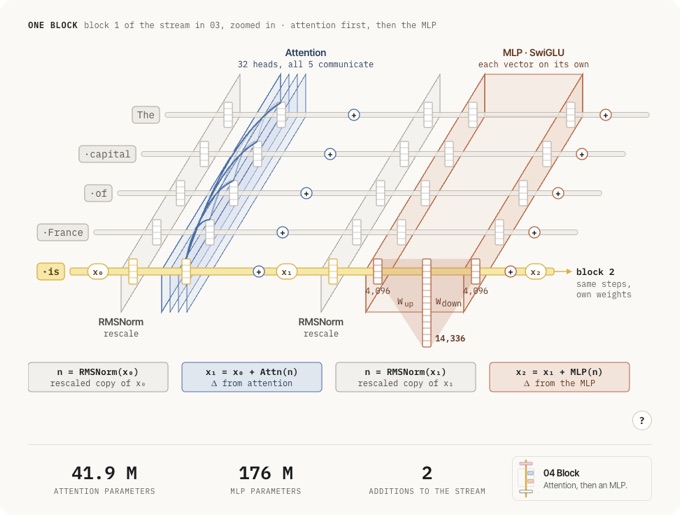
Inside a transformer
How tokens are generated from a prompt like “Tom opened a new bank…”, including explainers on algorithmic speed-ups like speculative decoding.
Start →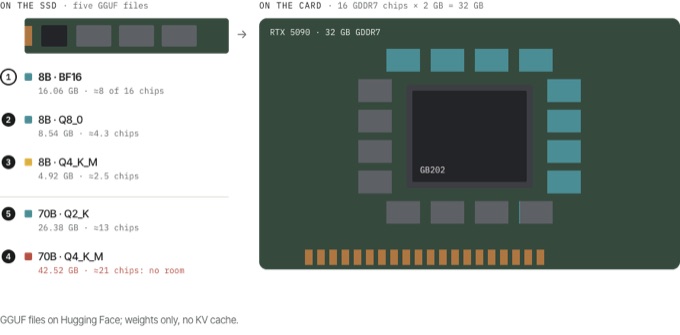 COMING SOON
Home GPU vs data centre
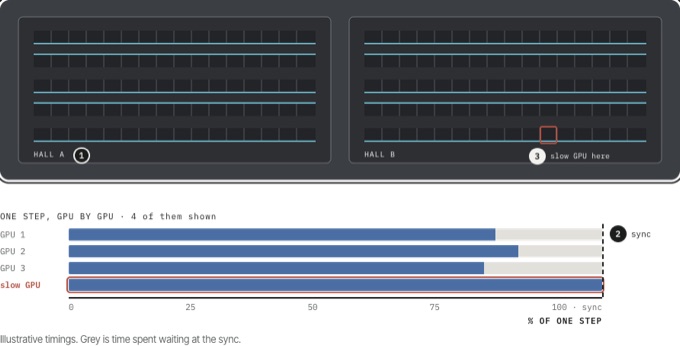
One user can’t keep an entire GPU busy, so data centres batch user requests. This shows how LLMs are deployed to your own GPU vs distributed at the data-centre level.
 COMING SOON
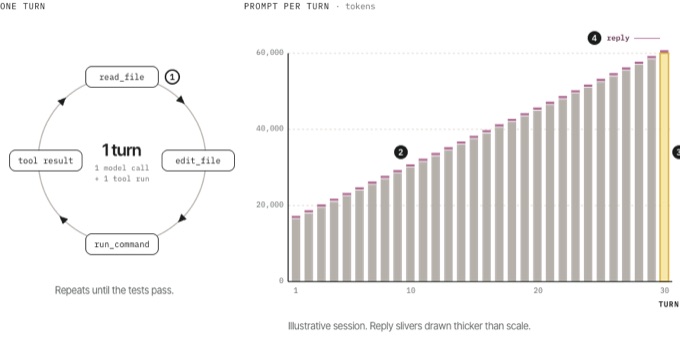
How a coding agent works
An agent is a loop around an LLM: every turn is a new, longer request.
 COMING SOON
Where does the time go?
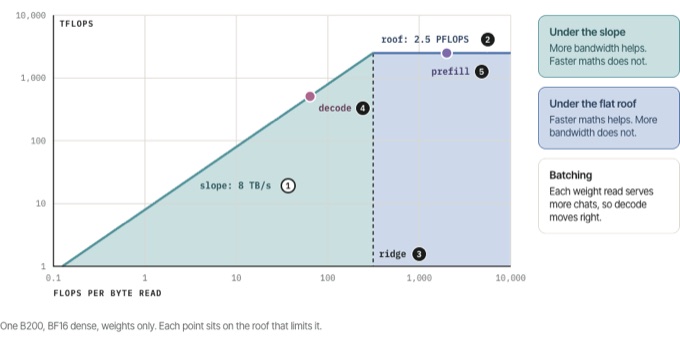
Breaking down a request’s latency (i.e. a roofline analysis) helps identify bottlenecks. Usually a workload is constrained on one of these: compute, memory, CPU, network, queuing.
 COMING SOON
Training a frontier model
From the compute budget to a released frontier-class model.
 COMING SOON
Measuring a system
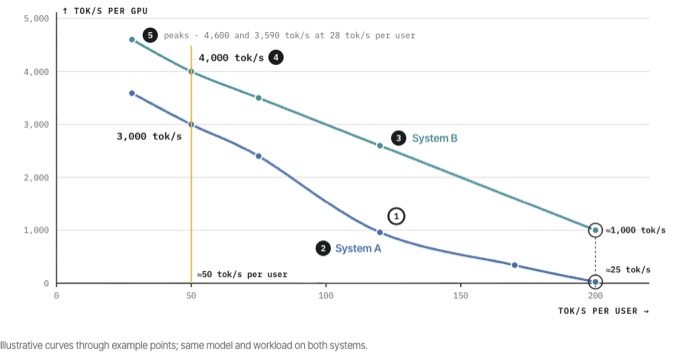
A method of analysis to measure the performance of variable, distributed systems.
 COMING SOON
From sand to slop
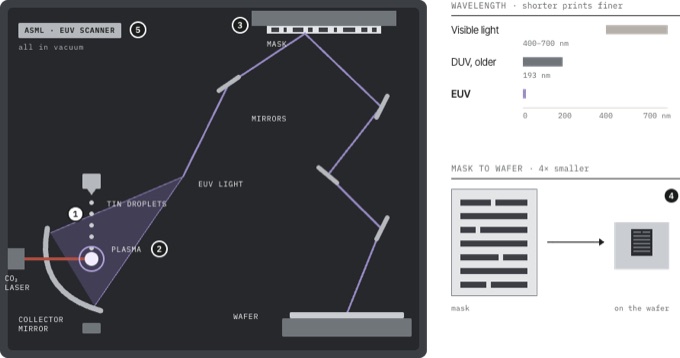
Chip design, silicon wafers, lithography, HBM and packaging, rack assembly, slop.